AI Data Labeling Services
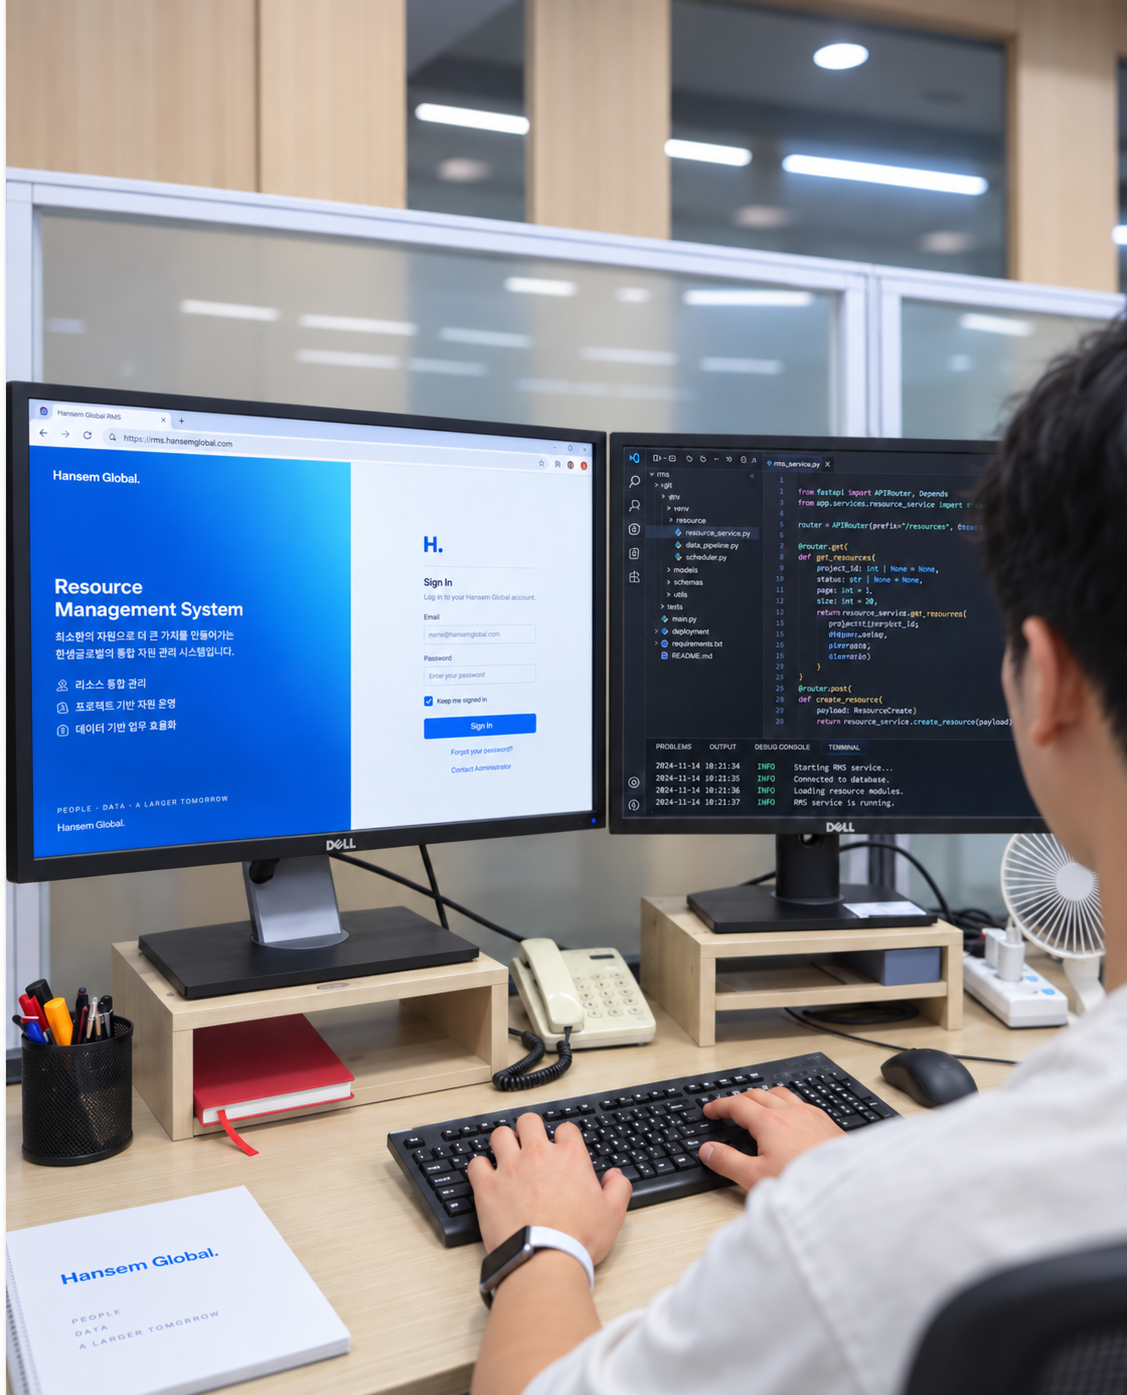
Hansem Global delivers large-scale AI data labeling across text, audio, image, and video, supported by trained specialists, structured quality control, and our proprietary Resource Management System (RMS).


Hansem Global delivers large-scale AI data labeling across text, audio, image, and video, supported by trained specialists, structured quality control, and our proprietary Resource Management System (RMS).
Large-scale AI data projects often require different languages, skills, qualifications, and availability at short notice. We select contributors based on project-specific requirements rather than relying on a fixed or anonymous crowd workforce.
Hansem RMS connects resource registration, condition-based search, candidate selection, availability checks, assignment tracking, and communication history in one operational system. This helps project managers identify deployable resources quickly and keep large teams under control as requirements change.
AI data projects can change rapidly in volume, language, format, and task complexity. Project managers coordinate instructions, staffing, schedules, and issue handling so teams can be reorganized as requirements evolve without losing visibility or consistency.
Clear work guidelines, staged review, and ongoing performance monitoring help maintain consistent output across large datasets and distributed teams. Resource history and project feedback can also support better assignment decisions for future work.
Text is the most widely used data type in AI training, and the type we handle most. We tag user intent, sentiment, context, and key entities so models can accurately interpret natural language, drawing on expert linguists across Asian languages and beyond. This kind of high-quality training data strengthens NLP applications like chatbots, sentiment analysis, and information extraction.
Tagging intent, sentiment, context, and key entities.

Spoken language varies by environment, intonation, dialect, and speaker. Our audio labeling prepares speech data for voice AI by transcribing audio accurately and labeling metadata such as emotion, language, and dialect. We also identify non-speech sounds, such as a glass breaking, to broaden recognition coverage. This kind of data supports ASR and voice-assistant development, and is also used in security and incident-response systems.
Accurate transcription with emotion, language, and dialect labeling.
Image labeling provides the training data behind computer vision, facial recognition, and other visual AI. We label objects, facial landmarks, and image-level classes so models can detect and classify visual information reliably. This kind of dataset is applied across autonomous driving, security monitoring, manufacturing quality inspection, and facial recognition development.
Labeling for object detection, classification, and facial landmarks.
Video labeling turns dynamic, frame-by-frame visuals into training data for vision AI. We track object motion across frames and label human and object actions and key events. This kind of data matters for models that must work in real-world conditions: autonomous driving, action recognition, CCTV surveillance, and event detection.
Object tracking with action and event labeling across frames.
Case studies, guides, and articles related to this service.
Why Language Service Providers Are Critical to Multilingual AI Data Labeling Projects
Data Labeling for AI Projects: A Practical Guide to Joining Global Initiatives
Translators in the Platform Era: How to Work with Freedom and Responsibility
What Data Work Does Physical AI Require?